AI research and products for Khmer
Khmer speakers should be able to use AI in their own language. We’re doing the research to make that possible, and sharing every model and dataset we make, free.
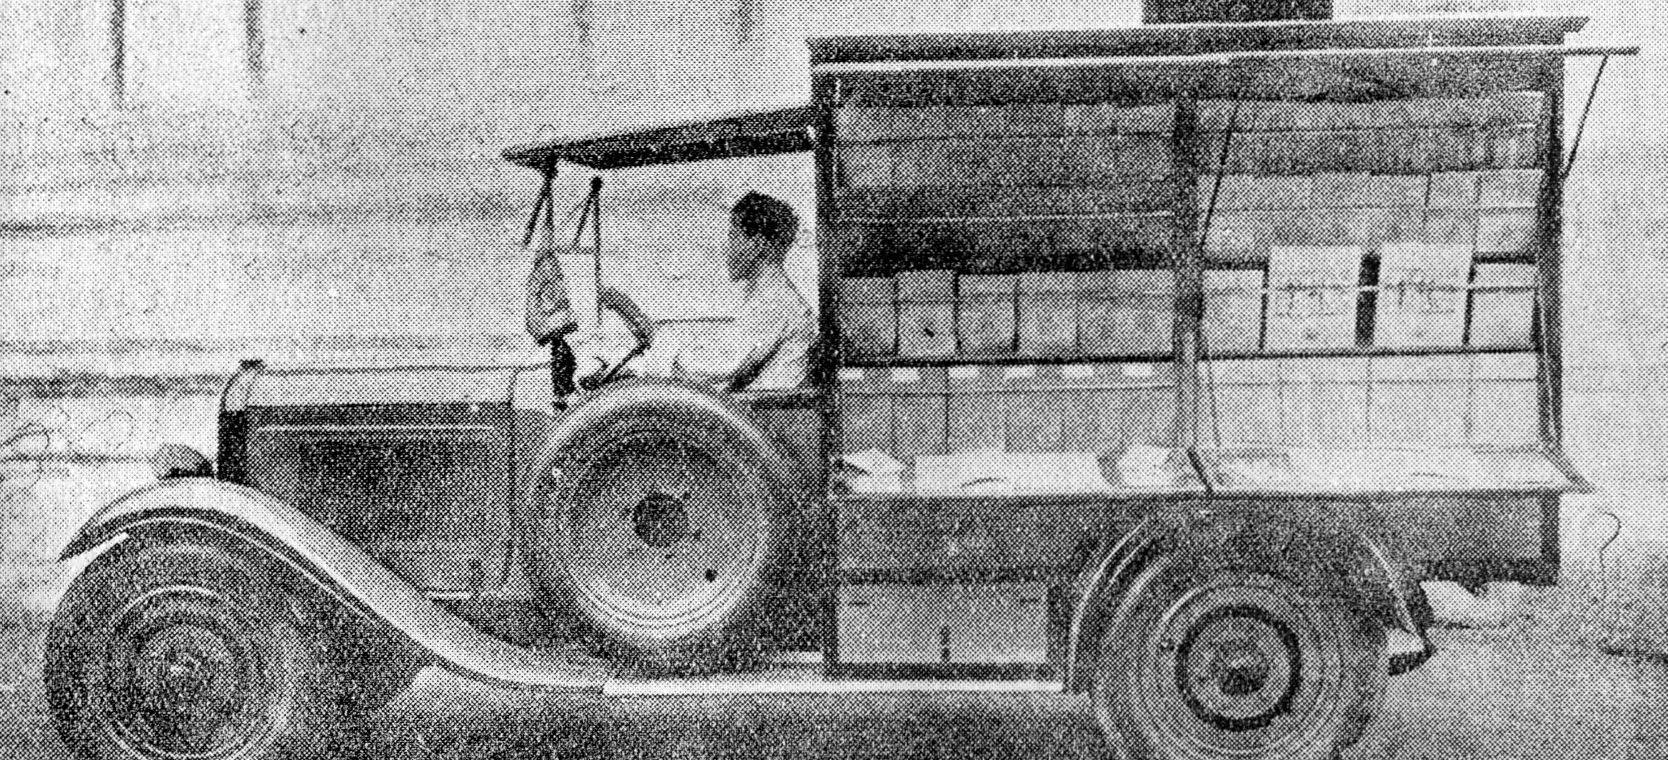
“Rolling Library” of the Institut bouddhique de Phnom Penh, 1930 · public domain
Our models
Demo live
Netra-OCR
Turns photos and scans of Khmer text into text you can copy, search, and edit.
Demo live
Netra-NMT
Translates between English and Khmer, in both directions.
Demo soon
AkaraAlpha
Type Khmer in Latin letters, the way you'd text it, and get it back in Khmer script.
Why Khmer
More than 16 million people speak Khmer. Most AI still treats it as an afterthought.
There’s little public data to train on, and tools built for English stumble on a script where consonants stack and words run together without spaces.
We build for Khmer from the start, and publish everything, so the next person working on Khmer doesn’t have to start from zero.
Our commitments
Built for the people who read and write Khmer.
- Read more →
You won't need an account, an API key, or a credit card to use anything we make. Code, weights, and reports are released under licenses that allow commercial use, changes, and redistribution.
This isn't a trial period. We won't lock the work away later, even if a business reason to do so comes up. Khmer-language tools shouldn't need anyone's permission to build on.
No account, no API key, no paid tier. Everything we release is yours to use and build on.
You won't need an account, an API key, or a credit card to use anything we make. Code, weights, and reports are released under licenses that allow commercial use, changes, and redistribution.
This isn't a trial period. We won't lock the work away later, even if a business reason to do so comes up. Khmer-language tools shouldn't need anyone's permission to build on.